Check a two-column PDF by following each paragraph to its continuation. If sentences from the opposite column interrupt it, repair the reading order before summarizing or indexing the text.
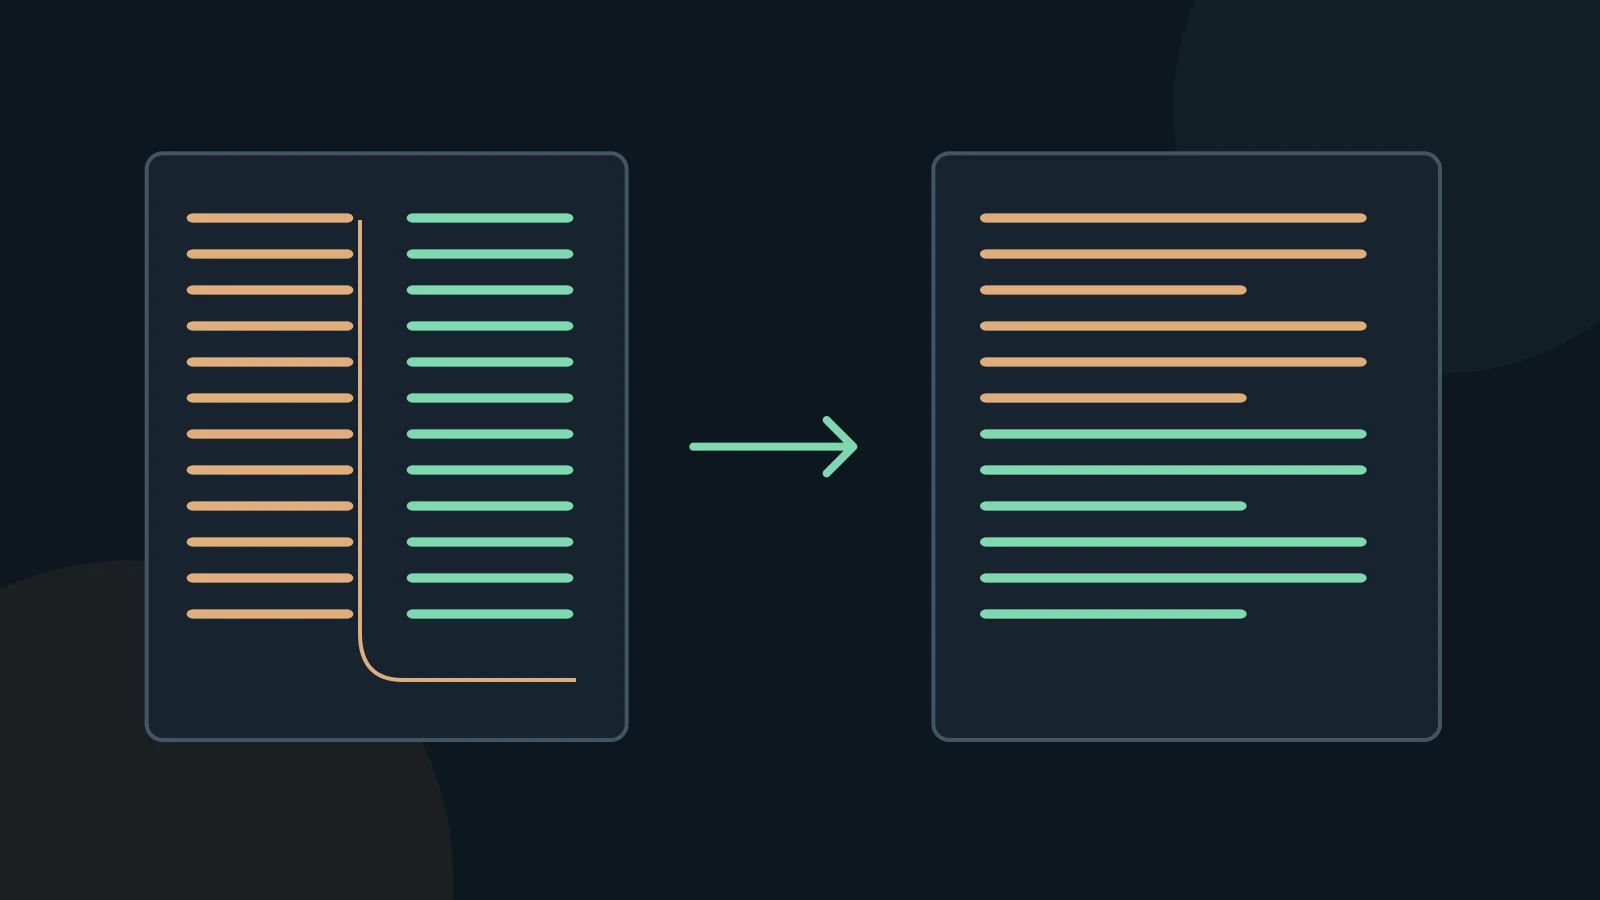
Recognize interleaved columns
A common failure alternates a line from the left column with a line from the right. Another places a caption halfway through a sentence. Apache PDFBox explains that the drawing sequence in a PDF need not match the reading sequence. Position sorting is a tool, not proof of a correct article.
Start with a page whose layout changes: a full-width title above two columns, a large figure, or the end of a section. Verify whether the intended path is down the left column and then down the right. Some documents use another sequence; follow the source.
Restore one page before the whole paper
- Locate the first and last sentence of each column in the PDF. Find the same sentences in Markdown.
- Move complete paragraph blocks into source order. Do not join lines from different columns merely because their heights match.
- Place full-width headings before the section they introduce. Keep captions with their figures and footnotes linked to their markers.
- Read the last paragraph on one page and the first on the next together. Check that a page break has not duplicated or dropped a continuation.
Keep evidence of the repaired order
Imagine the left column ends “The second experiment” and the next line continues “used a smaller sample.” A right-column sentence about funding between those fragments is a layout error. Restore the complete sentence, then inspect the surrounding paragraph rather than moving a single word in isolation.
Retain useful section names and page references when preparing research notes. If a sidebar is independent, label it as a sidebar instead of blending it into the argument. For right-to-left and mixed-language pages, verify the intended sequence visually; a left-to-right rule is not universal.
Review before using the result
A conversion is a working copy. Keep the original PDF and compare the passages you will quote, calculate from, or give to an AI assistant. A successful export does not establish that the text is complete or correct.
MD Factory converts documents to Markdown on Windows. Complex PDF tables use layout heuristics; merged cells and multiline content can need manual repair. OCR accuracy depends on the source image and text. This guide does not promise automatic cleanup or a particular recognition accuracy.
Questions and answers
Will running OCR fix reading order?
It may change the extraction result, but it can also introduce character errors. Diagnose a layout problem before replacing usable digital text.
Can I trust a coherent AI summary?
A fluent summary can hide interleaved source text. Verify the text order itself before asking for a summary.
Sources and verification
Sources checked on November 3, 2026. The instructions below describe a manual review workflow, not additional MD Factory controls.